<
How-To & Tutorials
Staging to Live: 12 Things That Only Break After the DNS Switch
Staging to Live: 12 Things That Only Break After the DNS Switch
☰ Table of Contents
The staging site looked perfect on Friday. By Monday morning the client had a blank white page, the contact form was emailing a staging inbox nobody reads, and Google was indexing staging.clientdomain.com instead of the real site. Nothing on the staging to live checklist they used had covered any of it, because their checklist was written for the design phase, not the switch.
This is the list we now run instead. It is built around one uncomfortable fact: most launch failures are not design failures. They are environment failures, and they only appear in the two hours after DNS changes, when the site is publicly reachable but nothing has been re-tested against the real domain. Every item below has broken a real handoff at some point, ours included.
Why the staging site never catches these
Staging is a different environment wearing the same clothes. It runs on a different host, usually a different PHP and database version, often a different CDN and cache layer, and it lives on a subdomain. That difference is the whole point, and it is also why it hides the failures that matter.
Three structural reasons staging lies to you:
- URLs are baked in. WordPress, Shopify apps and most page builders store the site URL in the database. Every internal link, image path and canonical tag that staging generates points at the staging hostname until the database is updated. You will not see this on staging, because there it is correct.
- Your browser is lying too. You have visited staging fifty times. CSS, JS and images are cached locally. After you switch, the first person to load the site is a stranger with an empty cache, and that stranger sees what your cache has been hiding. Always test post-switch in a private window and on a phone that has never opened the site.
- Nothing is chasing you. Staging has no sitemap submitted, no analytics, no ad pixels, no search console. Live does. Things that are inert in staging start firing the moment real crawlers and real tracking scripts arrive.
That is the mental model to hold: staging proves the design works, not that the switch works. The two are separate jobs and need separate tests. We covered the design-side testing in our contact form checklist, which is the right prep before this article, not a replacement for it.
The pre-switch pass: 30 minutes, 8 checks
Do this in the hour before you touch DNS. All eight are cheap, and all eight prevent an entire class of post-switch panic.
| # | Check | Why it saves you |
|---|---|---|
| 1 | Lower the DNS TTL to 300 seconds, at least 24h ahead | Rollback that would take hours instead takes minutes |
| 2 | Export a full backup: files and database | Your only real undo button |
| 3 | Search the database for the staging hostname; note every table that holds it | Tells you exactly what a search-replace must touch |
| 4 | List every form’s recipient address and every API key | These are the two things most often left pointing at staging |
| 5 | Confirm the live SSL certificate is issued before the switch, not after | Avoids the cert-before-DNS chicken-and-egg stall |
| 6 | Copy the current live site’s redirect rules into your notes | Old URLs almost always need to keep working |
| 7 | Confirm who controls the registrar account, in writing | The number-one reason handoffs stall for a week |
| 8 | Set a maintenance window you actually told the client about | Turns a surprise into a plan |
The 12 failures that appear after the switch
This is the core list. Each one is specific to the post-switch window, and each has a one-line detection test you can run in a browser.
- Site URL still the staging hostname. Symptom: links send you to staging, or the site redirects in a loop. Test: click the logo from an inner page and read the address bar.
- Mixed content. Symptom: padlock disappears, some images silently vanish. Test: open the browser console and look for blocked-content warnings.
- Canonical tags pointing at staging. Symptom: Google indexes the wrong host. Test: view source and search for the old hostname.
- Stale cached HTML. Symptom: the client sees the old site, or half of each. Test: private window plus a hard reload, then check the CDN’s cache status header.
- Forms emailing a staging address. Symptom: enquiries disappear. Test: submit once from a real phone and confirm arrival at the client’s inbox, not yours.
- Transactional email failing authentication. Symptom: order receipts land in spam. Test: send yourself a real receipt and inspect the headers for SPF and DKIM pass.
- Absolute image and file URLs left on the staging path. Symptom: broken thumbnails only on pages you did not open during QA. Test: crawl a sitemap of 20 URLs, not 3 pages.
- A “discourage search engines” flag still enabled. Symptom: nothing ranks for six weeks. Test: check the robots meta on a live page, not a setting screen.
- Analytics and pixels double-firing. Symptom: inflated traffic, duplicate conversions. Test: one page load should produce one pageview, not two.
- Redirect chains and 404s from old URLs. Symptom: rankings drop after the migration. Test: run the old site’s top ten URLs through a redirect checker.
- Uploads folder permissions. Symptom: images upload but do not display. Test: upload one file from the live admin and view it on the front end.
- Backups not scheduled on the new host. Symptom: silent risk, discovered at the worst time. Test: confirm one completed backup exists, not that a plugin is installed.
Two of these deserve their own sections, because they are the ones that cost the most time and are discussed least: the www/SSL interaction, and email authentication.
DNS, www and the mixed-content trap
A DNS switch is really four records moving, and each one fails differently. Get the pattern right once and you stop guessing:
| Record | Common mistake | Result |
|---|---|---|
| A / AAAA (apex) | Pointing at the old host by habit | Half the visitors see old content |
| CNAME (www) | No redirect rule for www vs non-www | Duplicate versions of every page |
| CAA | Restricting issuers to the old CA | Certificate renewal fails weeks later |
| TXT (SPF, DKIM, DMARC) | Dropped during migration | All site email starts landing in spam |
Pick one hostname as canonical and redirect the other with a single permanent hop. Not a chain, not a meta refresh: one 301. Then verify the certificate covers both names. A cert issued for the apex only will throw a warning for anyone who types www, and that warning converts visitors into ex-visitors faster than any design flaw.
Mixed content is the same idea applied to protocols. Any hardcoded http:// asset on an https:// page gets blocked by the browser. Builders and page templates are the usual suspects, because older saved layouts keep absolute http URLs. Search the database for http:// before the switch, not after, and fix them in one pass. If your HTTPS is fine but the message still feels off to clients, that trust question is worth understanding properly, and our handoff checklist covers what to send alongside the new site.
Email breaks silently: SPF, DKIM and DMARC
This is the failure that generates the angriest client message, because it is invisible from the website and it affects their customers directly.
When a site moves host, the sending infrastructure often moves with it. If the new host’s sending IP is not included in the domain’s SPF record, and no DKIM signature is published, a share of the client’s transactional mail (order confirmations, password resets, invoice notifications) gets filtered as spam. Nothing on the site looks broken. The form submits fine. The email just never appears.
The 15-minute version of the fix:
- Ask the new host for their exact sending domains and IP ranges.
- Update the SPF TXT record to include them, keeping every existing legitimate sender.
- Publish the DKIM keys they provide, at the selector they specify.
- Make sure a DMARC record exists, even in monitor-only mode to start.
- Send one real test email to a Gmail address and read the authentication results in the headers.
The 48-hour watch list
Launch day is not the finish line; the two days after it are when indexing, campaigns and client traffic all hit at once. Here is the rhythm we follow.
| When | What to check | Pass looks like |
|---|---|---|
| Hour 0 | Homepage, one inner page, one form, one image upload, mobile private window | Everything renders on a device with no cache |
| Hour 1 | SSL padlock on both hostnames; console free of blocked content | No warnings anywhere |
| Hour 3 | Search Console: new property verified, sitemap submitted | Sitemap accepted without errors |
| Hour 6 | Old top-ten URLs redirect in one hop | No chains, no 404s |
| Day 1 | Analytics shows one pageview per visit; form mail arrived at the client | Numbers are sane, mailbox is not empty |
| Day 2 | First backup completed; crawler finds no staging hostname | Clean backup exists, zero leaks |
The staging-hostname sweep on day two is worth repeating late, because it catches the pages nobody clicked during launch QA. Crawl twenty URLs from the sitemap and search the rendered HTML for the old hostname. Any hit is a page that will confuse a client or a crawler later.
The rollback plan you write before you need it
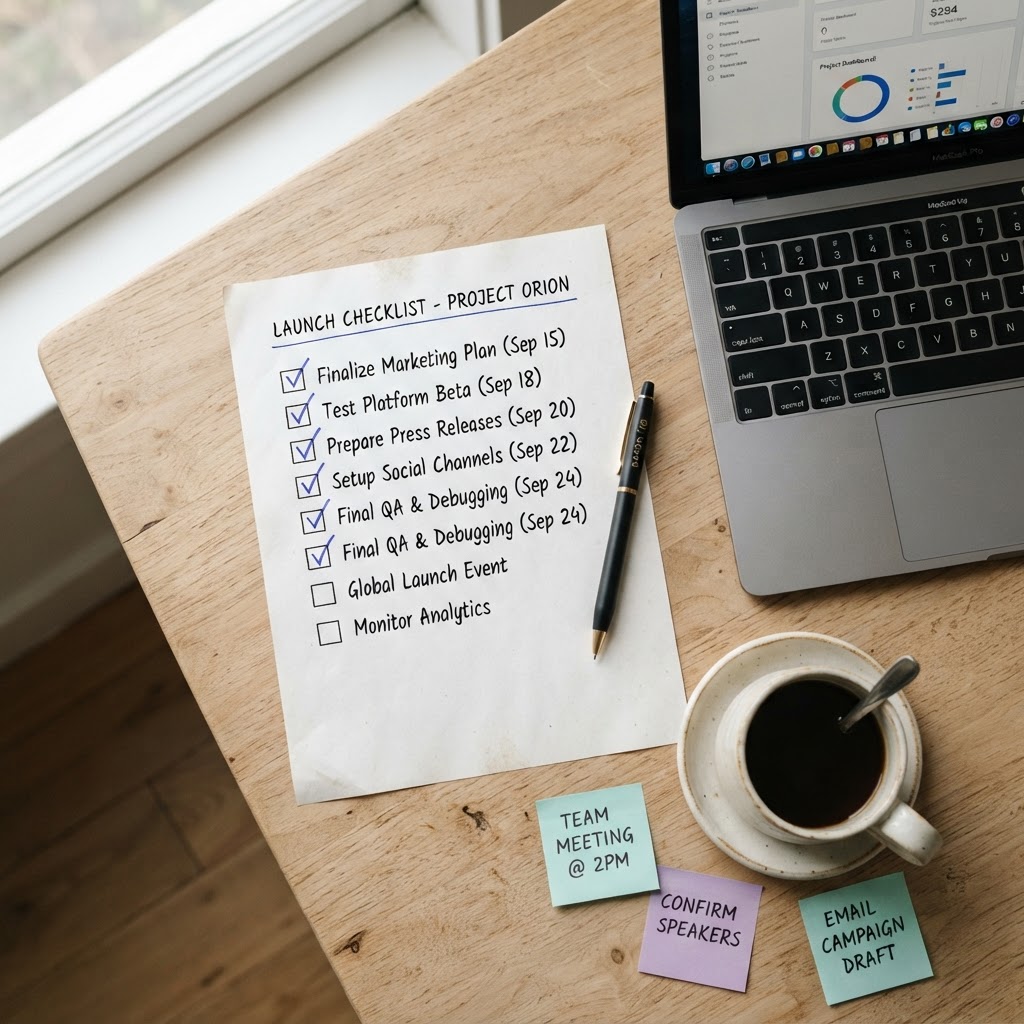
Rollback is not a feeling, it is three written steps with an owner. Write them down before the switch and the worst case becomes boring.
- DNS revert. Restore the previous A and CNAME values. This is why TTL was lowered a day earlier.
- Content revert. Restore the pre-switch database and files, or re-point the host if the content is intact elsewhere.
- Communication. One short message to the client: what broke, what you did, what happens next.
Decide in advance what counts as “bad enough to roll back.” Our line: if the checkout or the lead form is broken for more than 20 minutes with no clear fix, we revert first and debug second. A working old site beats a broken new one every single time, and clients remember how the recovery felt far longer than they remember the launch.
What to send the client on go-live day
The technical work is half of the handoff; the message is the other half. Send one short note containing four things:
- The live URL, and which version of the hostname is canonical.
- What changed on their side: logins, email settings, DNS access.
- What you will monitor for the next 48 hours, in plain language.
- What they should do if they see something odd: send a screenshot, not a guess.
Also hand over credentials in a form that survives contact with reality. A shared password sent in chat is still finding its way into someone’s inbox in three months. Use a password manager share link with an expiry, or a single-use secret link, and leave access revocation to a written checklist rather than memory.
If you write the checklist down once, you never re-derive it under pressure again. Ours lives in the project template, and it has been updated after every launch that went sideways. That is the honest version of a launch process: not a document that proves you were careful, but one that has absorbed your mistakes.
FAQ
How long does it take for a DNS switch to go live?
Usually between a few minutes and a few hours, depending on the TTL that was set before the change and on resolvers caching the old value. With a 300-second TTL, most of the world sees the new host within ten minutes. With the default 24-hour TTL, some visitors can still reach the old host a day later.
Should I switch DNS before or after fixing the site URL?
Fix the database and configuration first, switch second. If you point DNS at a site whose stored URL still says staging, visitors land in a redirect loop and you cannot fix it from the front end. Prepare the new environment fully, then move the records.
Why does the site look fine for me but broken for the client?
Cache. Your browser and possibly the CDN are serving stored copies of old CSS and HTML, or the client’s browser is serving an older page. Test in a private window, on a device that has never visited the site, and bust the CDN cache before you conclude anything is broken.
Do I need to keep the old URLs working after a redesign?
Yes, if the old URLs ever ranked or were linked. Map each old URL to its nearest new equivalent with a single 301 redirect. Skipping this is the most common cause of a traffic drop that looks like a Google penalty and is really just a pile of 404s.
How do I check whether form email is actually being delivered?
Submit the form from a phone on mobile data, then confirm the message appears in the destination inbox within a few minutes, and open the message headers to see SPF and DKIM pass. “The form said thank you” proves nothing about delivery.
What is the single most important post-switch check?
Load the homepage in a private window on a device that has never opened the site. That one action simulates your client, your client’s customers and every crawler at once, and it catches most of the twelve failures above in under a minute.
<